Clockwork.io Introduces A New Class of Fault Tolerance to End Failure-Driven GPU Waste in AI Training

New TorchPass solution addresses a multi-million dollar challenge with AI infrastructure; uses Live GPU Migration to keep large-scale AI training running through hardware failures instead of forcing costly restarts
PALO ALTO, CA / ACCESS Newswire / March 11, 2026 / Clockwork.io, the leader in Software-Driven AI Fabrics™- a programmable, vendor-neutral software layer that optimizes large-scale GPU clusters for real-time observability, fault tolerance, and deterministic performance-today announced the general availability of TorchPass Workload Fault Tolerance. This new class of software-driven fault-tolerance eliminates one of the most costly failure modes in large-scale AI training: catastrophic job restarts caused by infrastructure faults.
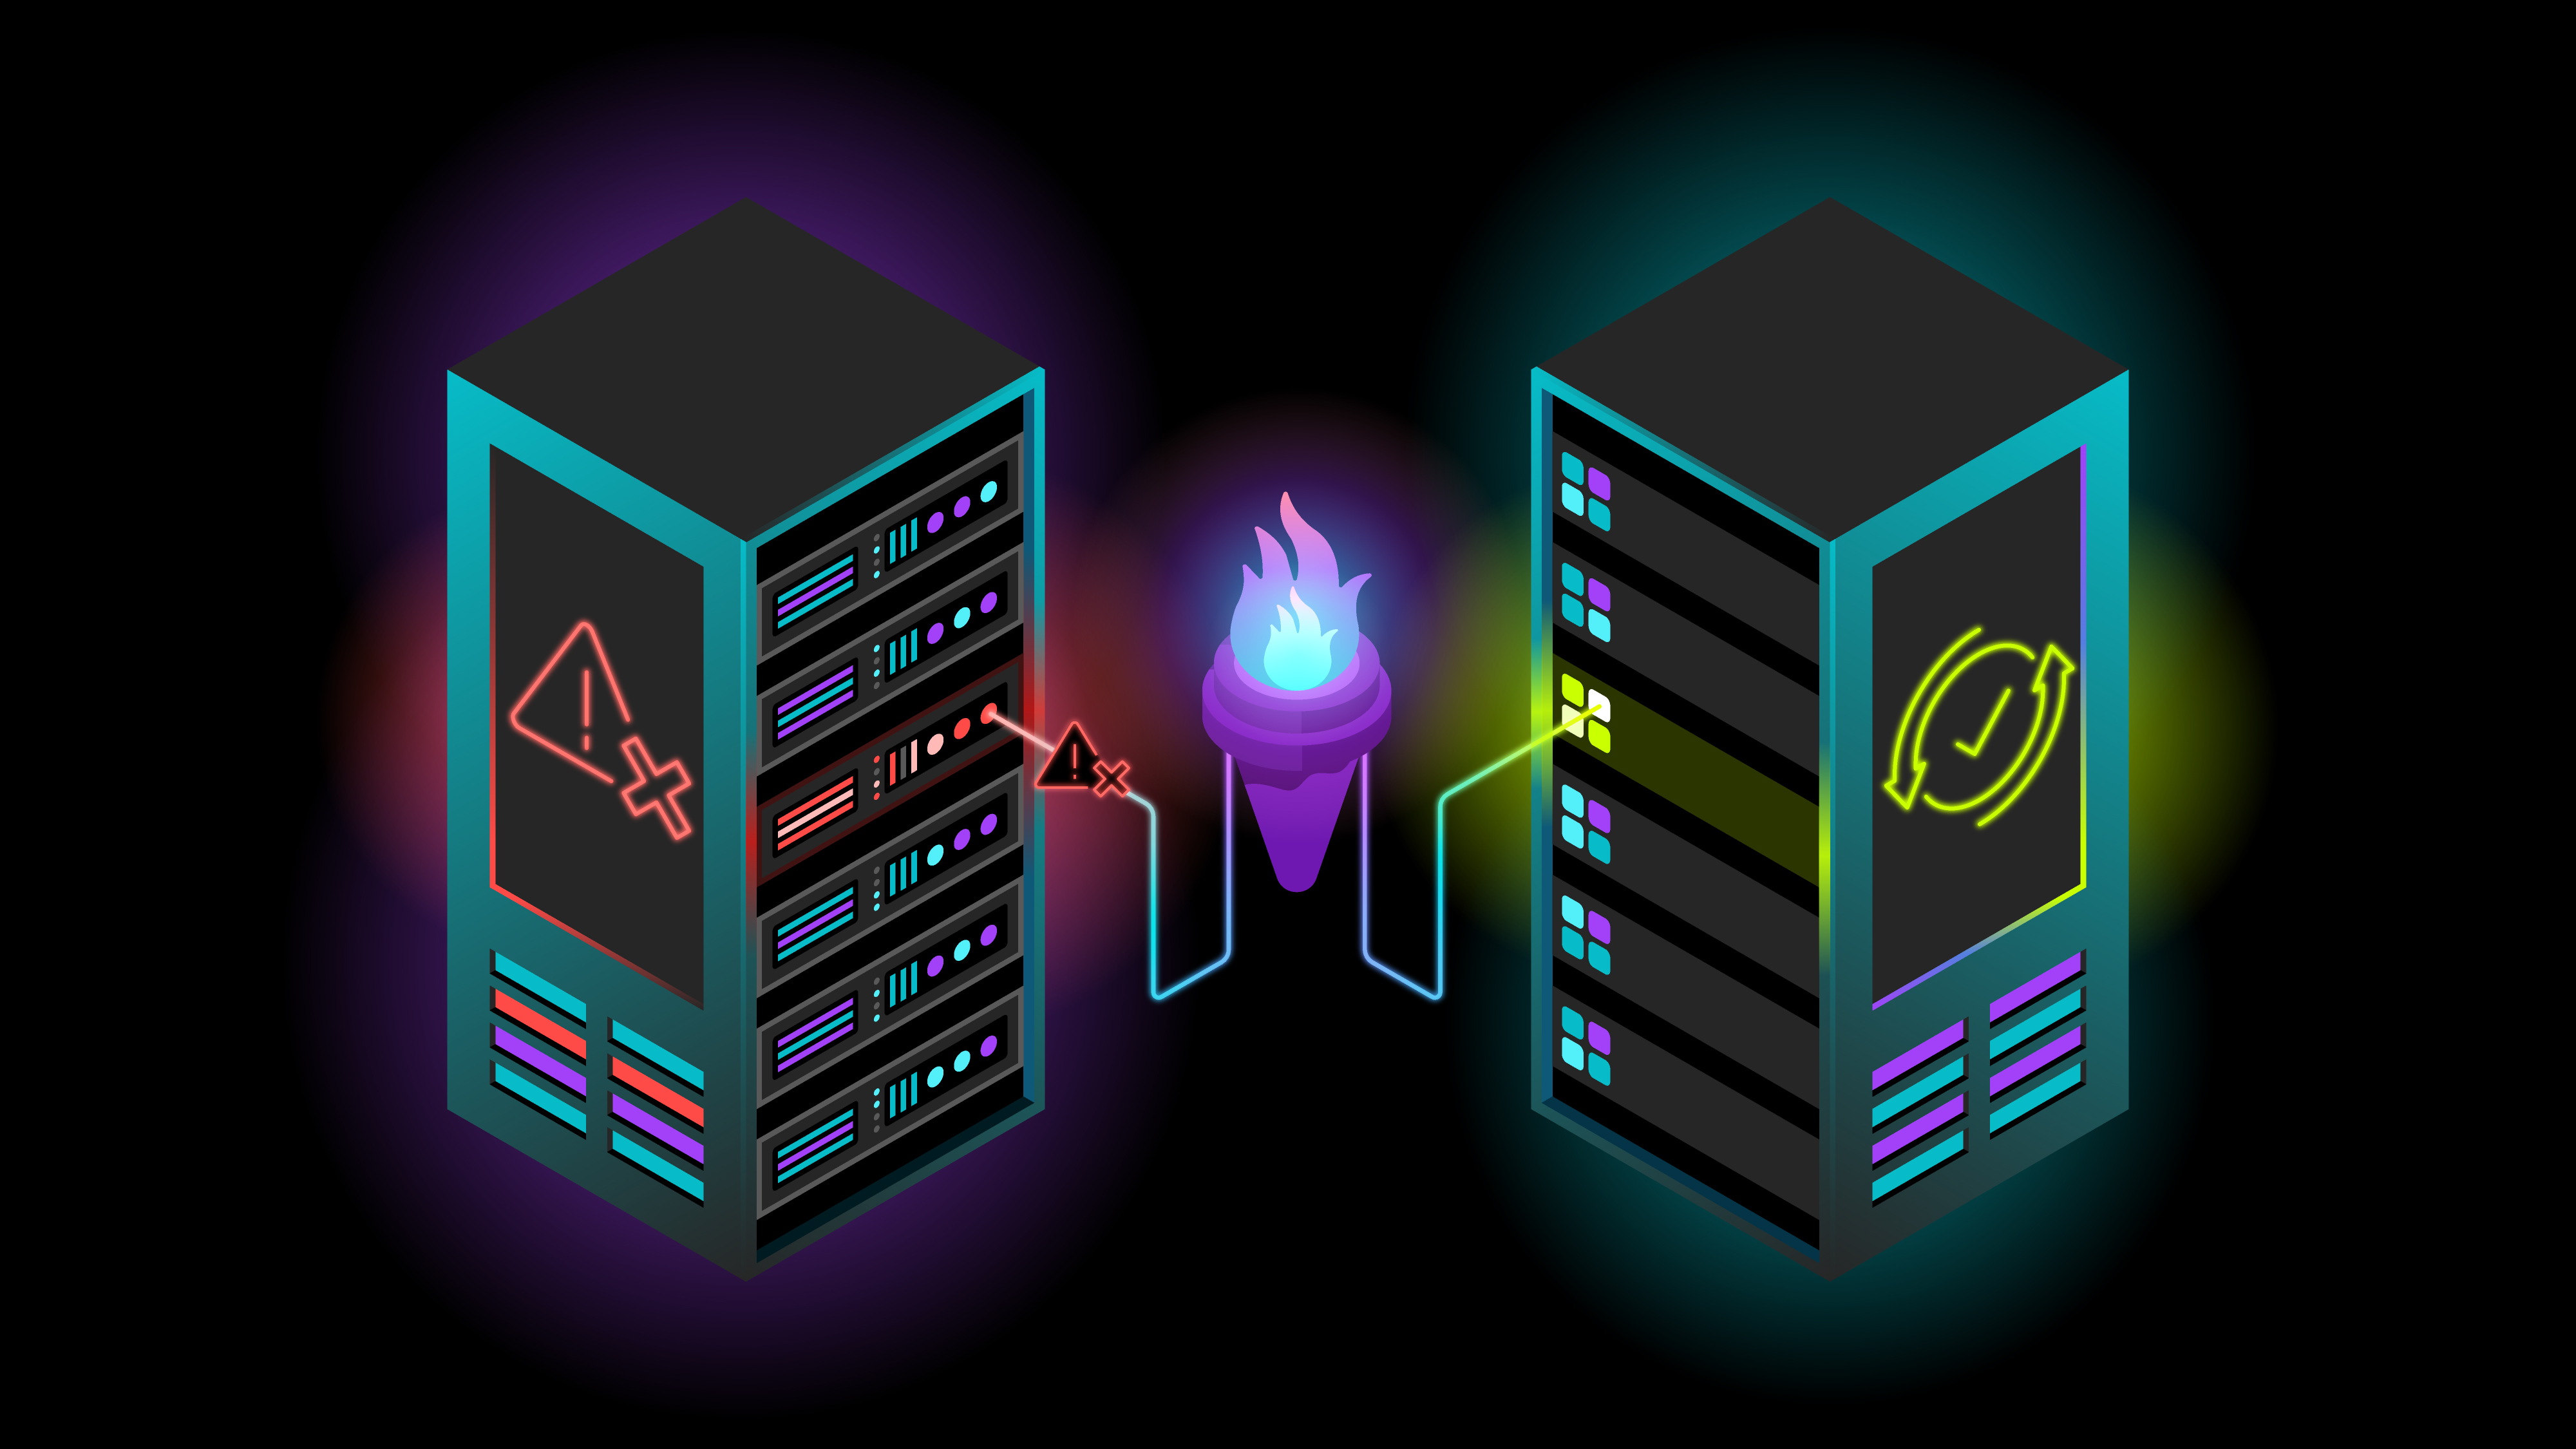
Delivered as a core capability of the Clockwork.io FleetIQ™ platform, TorchPass applies the principles of Software-Driven AI Fabrics to distributed training, using Live GPU Migration to allow workloads to continue running through GPU failures, network disruptions, driver bugs, and even full node crashes-without checkpoint restarts or lost progress.
"Companies are investing billions in next-gen chips, yet the costs of running distributed AI jobs remains grossly inflated because the ecosystem has accepted failure as a constant," said Suresh Vasudevan, CEO of Clockwork.io. "We built TorchPass to fundamentally reject that premise. Instead of treating failure as inevitable and restarting after the fact, TorchPass makes infrastructure faults invisible to the workload-training continues through failures transparently, in software. For a typical 2,048-GPU deployment, that translates into over $6 million a year in recovered compute. This is what our Software-Driven AI Fabric approach was designed to deliver: fault-tolerant AI infrastructure."
Dylan Patel, Founder and CEO of SemiAnalysis agreed that large-scale training jobs are limited by interruptions.
"As Blackwell clusters roll out with an NVL72 domain, and we look to the future with Rubin Ultra's NVL576 domain, the idea that a single GPU error or network link flap can take down an entire run is totally unacceptable," said Patel. "TorchPass solves a huge challenge with cluster reliability: it provides transparent failover and live workload migration that keeps MFU high, which in turn drives better GPU economics."
Why AI Training Fails at Scale
Distributed AI training remains one of the most failure-prone workloads in modern infrastructure. As cluster sizes grow, fragility increases sharply. Research from Meta FAIR shows that mean time to failure drops to 7.9 hours in a 1,024-GPU cluster and to just 1.8 hours at 16,384 GPUs. This means that for most large, AI-focused enterprises or AI clouds, failure-driven restarts are completely inevitable - making this a major barrier to scaling AI's impact.
Each failure forces training jobs to roll back to the most recent checkpoint, discarding minutes or hours of completed work and wasting additional time on manual intervention, reprovisioning resources and restarting training. These restarts silently cap GPU utilization, making reliability one of the largest hidden costs in AI infrastructure.
TorchPass addresses this problem by proactively addressing costly AI workload failures, solving them before the job stops or needs to restart. Vital for enterprises running large AI workloads and AI clouds alike, TorchPass dramatically improves the reliability of workloads and cluster utilization. For AI clouds, who can now address impacted GPUs while preserving the training run as planned, this translates into better customer SLAs and overall AI cloud economics, improving their ability to protect margin and deliver new models sooner.
"Managing compute output across large-scale GPU clusters is vital to ensuring we're delivering reliable capacity to our customers. By using TorchPass we have the support of a company that focuses on resilience like it is a core business function: it replaces any specific failing GPU and keeps the rest of the job moving, rather than making one small problem impact our large-scale operations," said David Power, CTO of Nscale. "In our evaluation, Live GPU Migration preserved both run continuity and throughput under real fault conditions, which is exactly what you need to deliver predictable time-to-train and a better customer experience at scale."
How Live GPU Migration Works: Reliability Without Restart
TorchPass performs transparent, in-flight migration of impacted training ranks to spare resources when failures occur. TorchPass typically completes recovery in approximately three minutes while the training process continues uninterrupted.
It supports resilience across three failure scenarios:
Unplanned migration, handling sudden events such as kernel crashes, power failures, or GPU faults by reconstructing state from healthy replicas
Pre-emptive migration, triggered by early warning signals such as rising temperatures or ECC memory errors, enabling controlled migration before a hard failure
Planned migration, enabling maintenance, patching, and workload rebalancing without interrupting training
This approach reduces wasted training progress by 95%, cutting lost time from approximately three hours per day to under ten minutes in a 1,024-GPU cluster.
Jordan Nanos, Member of Technical Staff and lead author of ClusterMAX-SemiAnalysis' independent benchmark for large-scale AI training-stress tested Clockwork.io TorchPass and found it delivered leading performance and efficiency for large-scale distributed training, enabling users to reduce checkpointing overhead in training. He shared the following results:
"In our testing, Clockwork.io TorchPass delivered the fastest and most efficient fault-tolerant performance for a gpt-oss-120B training run. We used TorchTitan on a Kubernetes cluster with 64x H200 GPUs. During our testing we measured job completion time (JCT) and Model FLOPs Utilization (MFU) against a standard approach (checkpoint-restart) and the leading open-source fault-tolerant training framework (TorchFT). We simulated multiple hardware failures on the cluster in order to stress test the fault-tolerant training frameworks.
When compared to checkpoint-restart, TorchPass was significantly faster to recover from failures. This reduced overall JCT and maintained high MFU. And when compared to TorchFT, TorchPass had a significantly higher MFU. This reduced overall JCT while also maintaining an equal time to recover from failures.
Using TorchPass also has a downstream effect where it provides users with an opportunity to reduce or even remove checkpointing from their training code. This means larger effective batch sizes, lower risk of out of memory errors (OOMs), and less time spent thinking about storage. For a research organization, this can ultimately mean a faster time to reach their training objective," concluded Nanos.
Measurable Business Impact from Software-Driven Fault-Tolerance
For customers operating large AI clusters, the impact is immediate and measurable. In a typical 2,048-GPU H200 deployment, TorchPass Workload Fault Tolerance delivers over $6 million in annual savings by preventing wasted compute.
These savings come from eliminating hundreds of thousands of GPU-hours that would otherwise be lost to failure-driven restarts, cascading retries, and idle recovery time. By keeping training jobs running through infrastructure faults instead of restarting them, TorchPass converts lost GPU time into productive training, significantly improving the return on GPU investments that today often operate at just 30-50% of theoretical performance.
Enabling the Next Generation of AI Infrastructure
By making reliability a software-defined capability rather than a hardware constraint, TorchPass provides the operational confidence required to deploy next-generation, tightly coupled systems such as NVIDIA GB200 and GB300 NVL72 and future rack-scale systems, where dense architectures amplify the cost of even small failures.
TorchPass builds on Clockwork.io's prior release of Network Fault Tolerance, which applies the same Software-Driven AI Fabric principles to network resilience by transparently rerouting traffic around link failures.
Together, these capabilities form Clockwork.io's Software-Driven AI Fabric, a vendor-neutral software layer spanning network, compute, and storage. As modern AI workloads run on tightly coupled clusters where hundreds or thousands of processors must operate in coordinated lockstep, infrastructure behaves as a single system, where reliability and performance directly determine overall efficiency. By managing this complexity in software, Clockwork.io enables operators to run heterogeneous AI infrastructure as a unified platform-maintaining high utilization, predictable performance, and resilience while preserving the flexibility to evolve hardware and improve the economics of large-scale AI deployments.
To learn more about the launch of TorchPass, visit the Clockwork.io team in-person at NVIDIA GTC from March 16-19, Booth #205, or visit https://clockwork.io.
About Clockwork.io
Clockwork.io pioneers Software-Driven AI Fabrics™, delivering a programmable software layer that makes large-scale AI clusters observable, deterministic, and resilient by design to drive continuous workload progress and peak cluster utilization. Its FleetIQ platform enables enterprises to train, deploy, and serve the world's most demanding AI workloads faster, more reliably, and at lower cost. Companies including Uber, Wells Fargo, DCAI, Nebius, Nscale, and White Fiber trust Clockwork.io to power their AI infrastructure. Learn more at www.clockwork.io.
Media Contact
Dana Trismen
[email protected]
650-269-7478
SOURCE: Clockwork
View the original press release on ACCESS Newswire
(F.Schuster--BBZ)